Thin wrappers over SSE4.1, AVX and AVX-512 registers, so that one kernel template serves every SIMD width and the scalar path. More...
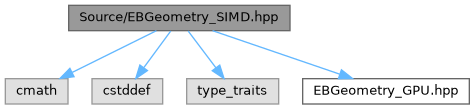
Include dependency graph for EBGeometry_SIMD.hpp:
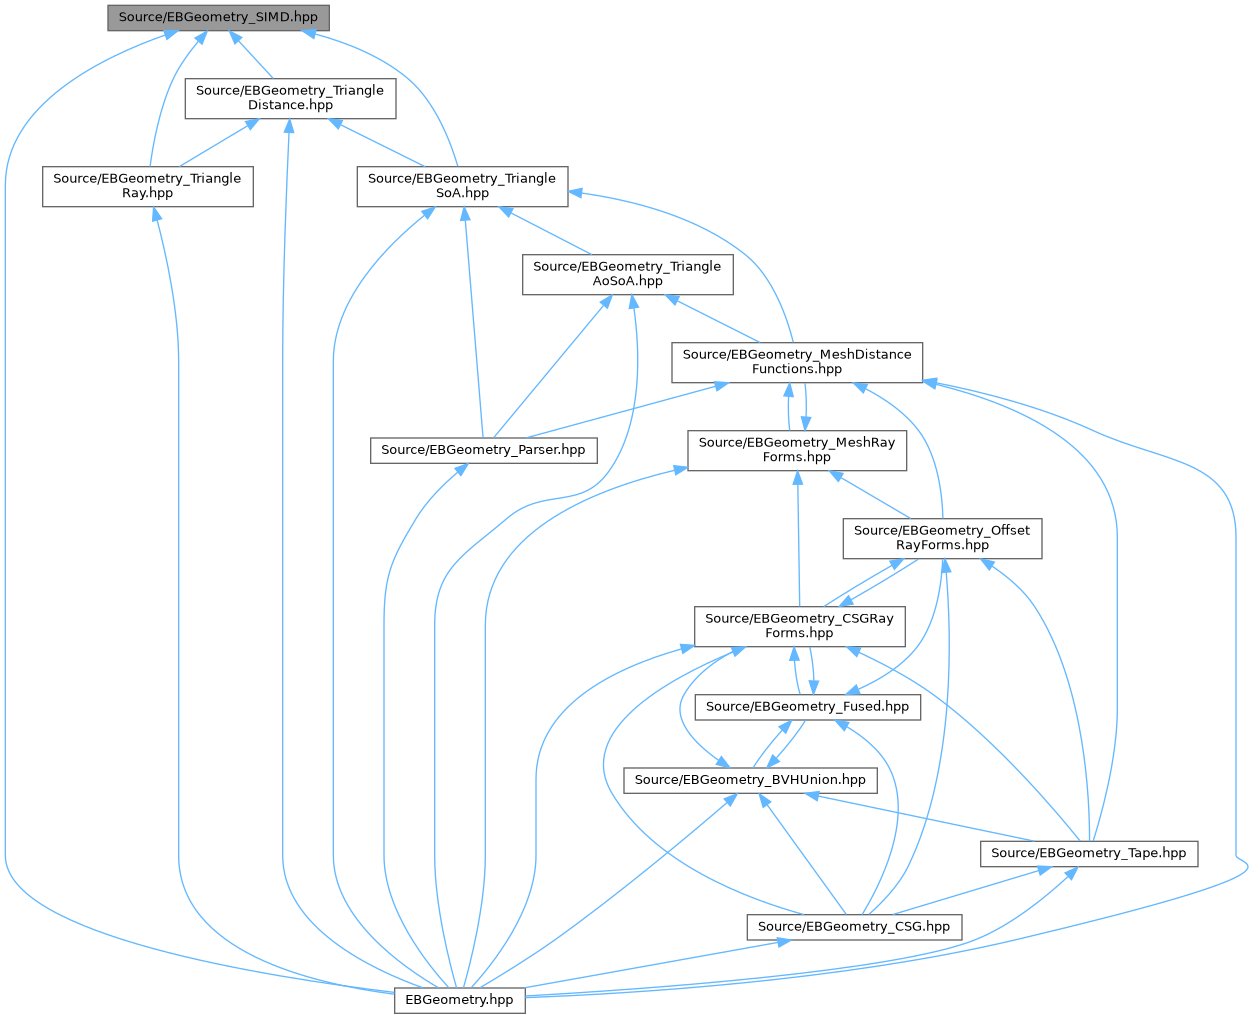
This graph shows which files directly or indirectly include this file:
Go to the source code of this file.
Classes | |
| struct | EBGeometry::SIMD::Scalar< V > |
| The scalar type of a scalar or pack type: T for T, and T for Pack<T, N>. More... | |
| struct | EBGeometry::SIMD::Scalar< Pack< T, N > > |
| The scalar type of Pack<T, N>. More... | |
Namespaces | |
| namespace | EBGeometry |
| Namespace containing all of EBGeometry's functionality. | |
| namespace | EBGeometry::SIMD |
| SIMD register wrappers and the scalar operations that mirror them. | |
Functions | |
| template<class T > | |
| T | EBGeometry::SIMD::select (const bool a_mask, const T a_ifTrue, const T a_ifFalse) noexcept |
Pick a_ifTrue where a_mask holds, else a_ifFalse (scalar form). | |
| bool | EBGeometry::SIMD::both (const bool a_lhs, const bool a_rhs) noexcept |
| Whether both conditions hold (scalar form). | |
| float | EBGeometry::SIMD::sqrt (const float a_x) noexcept |
| Square root (scalar form). | |
| double | EBGeometry::SIMD::sqrt (const double a_x) noexcept |
| Square root (scalar form). | |
| float | EBGeometry::SIMD::abs (const float a_x) noexcept |
| Absolute value (scalar form). | |
| double | EBGeometry::SIMD::abs (const double a_x) noexcept |
| Absolute value (scalar form). | |
| template<class T > | |
| constexpr size_t | EBGeometry::SIMD::WidestPack () noexcept |
| The widest SIMD register, in lanes of T, that this compilation pass has: 16 floats or 8 doubles under AVX-512F, 8 or 4 under AVX, 4 or 2 under SSE4.1, and 1 otherwise and in every device pass. | |
| template<class T , size_t W> | |
| constexpr size_t | EBGeometry::SIMD::NativeWidth () noexcept |
The lane count to evaluate a group of W values of T with: the widest register this compilation pass has whose lane count divides W, or 1 (the scalar path) if none does. | |
Detailed Description
Thin wrappers over SSE4.1, AVX and AVX-512 registers, so that one kernel template serves every SIMD width and the scalar path.
A kernel written against these operations – arithmetic operators, comparisons that give a mask, select(), sqrt() and abs() – compiles for a plain float or double (one lane, host and device) and for each SIMD::Pack the compiler's flags provide. The packs exist only in a host compilation pass: device code sees NativeWidth() == 1 and takes the scalar instantiation.
